

Product Evals in Three Simple Steps
After repeating myself for the $n^text{th}$ time on how to build product evals, I figured I should write it down.…
After repeating myself for the $n^text{th}$ time on how to build product evals, I figured I should write it down.…
2025 was an eventful year of progress. I doubled down on my health, had some pleasant career surprises, and my…
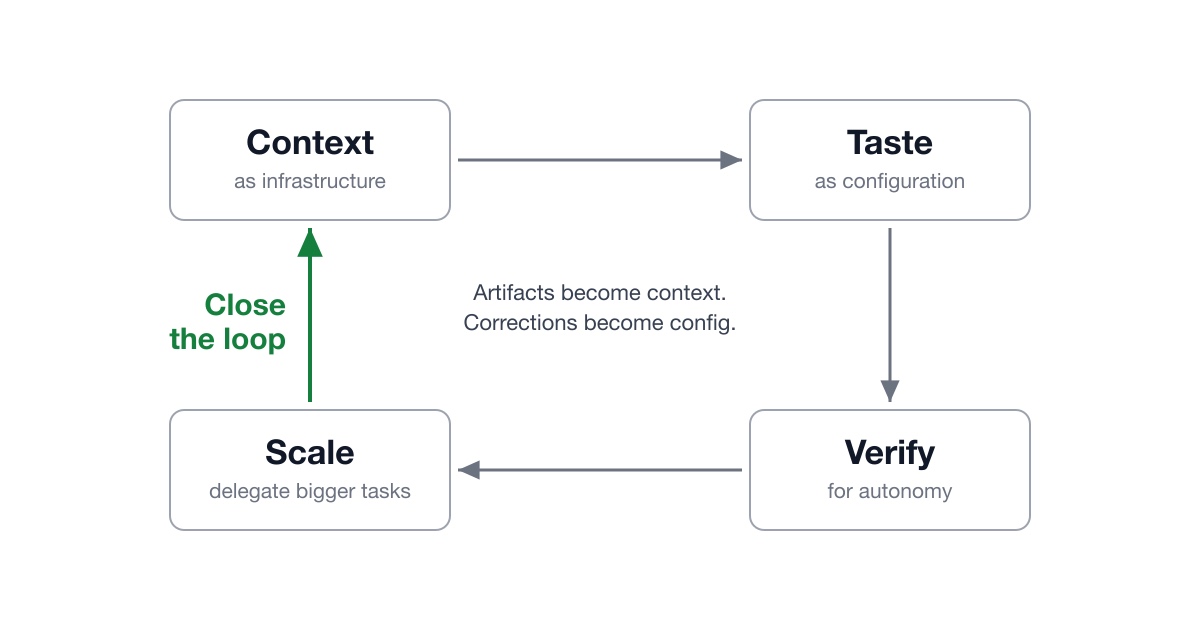
How can we work effectively with AI? What’s the workflow, how does it scale, and how do we improve our…
Build a threat model, discover vulnerabilities, verify, triage, and patch.
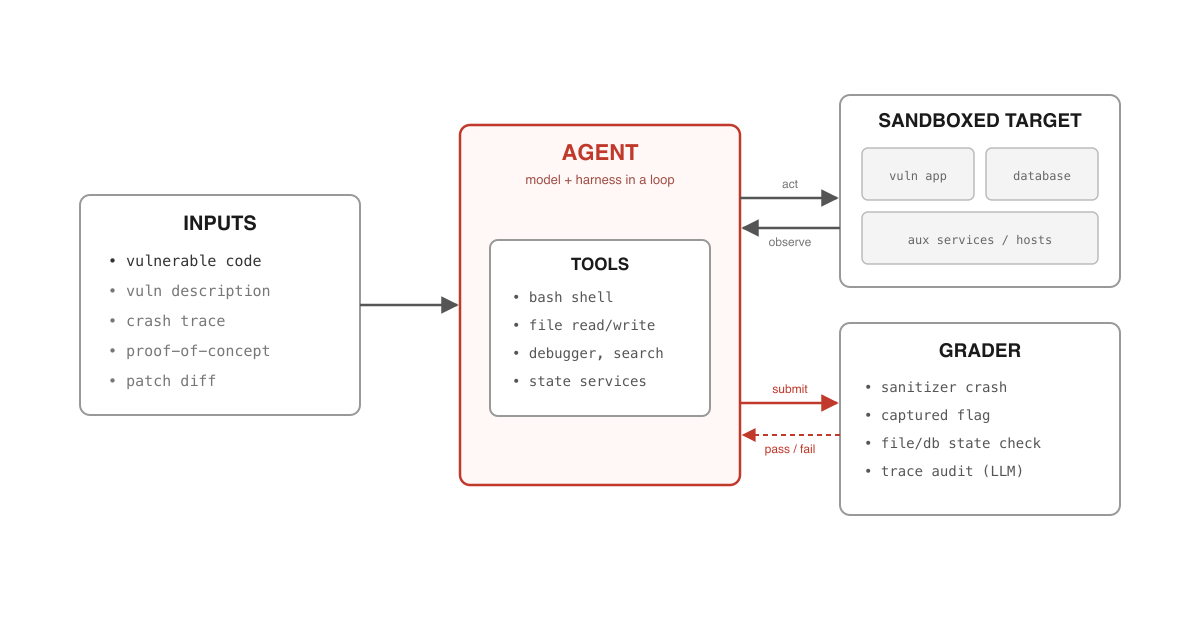
How do we evaluate if a model can find and exploit security vulnerabilities? How do we know when agents become…
Hallucination in large language models usually refers to the model generating unfaithful, fabricated, inconsistent, or nonsensical content. As a term,…
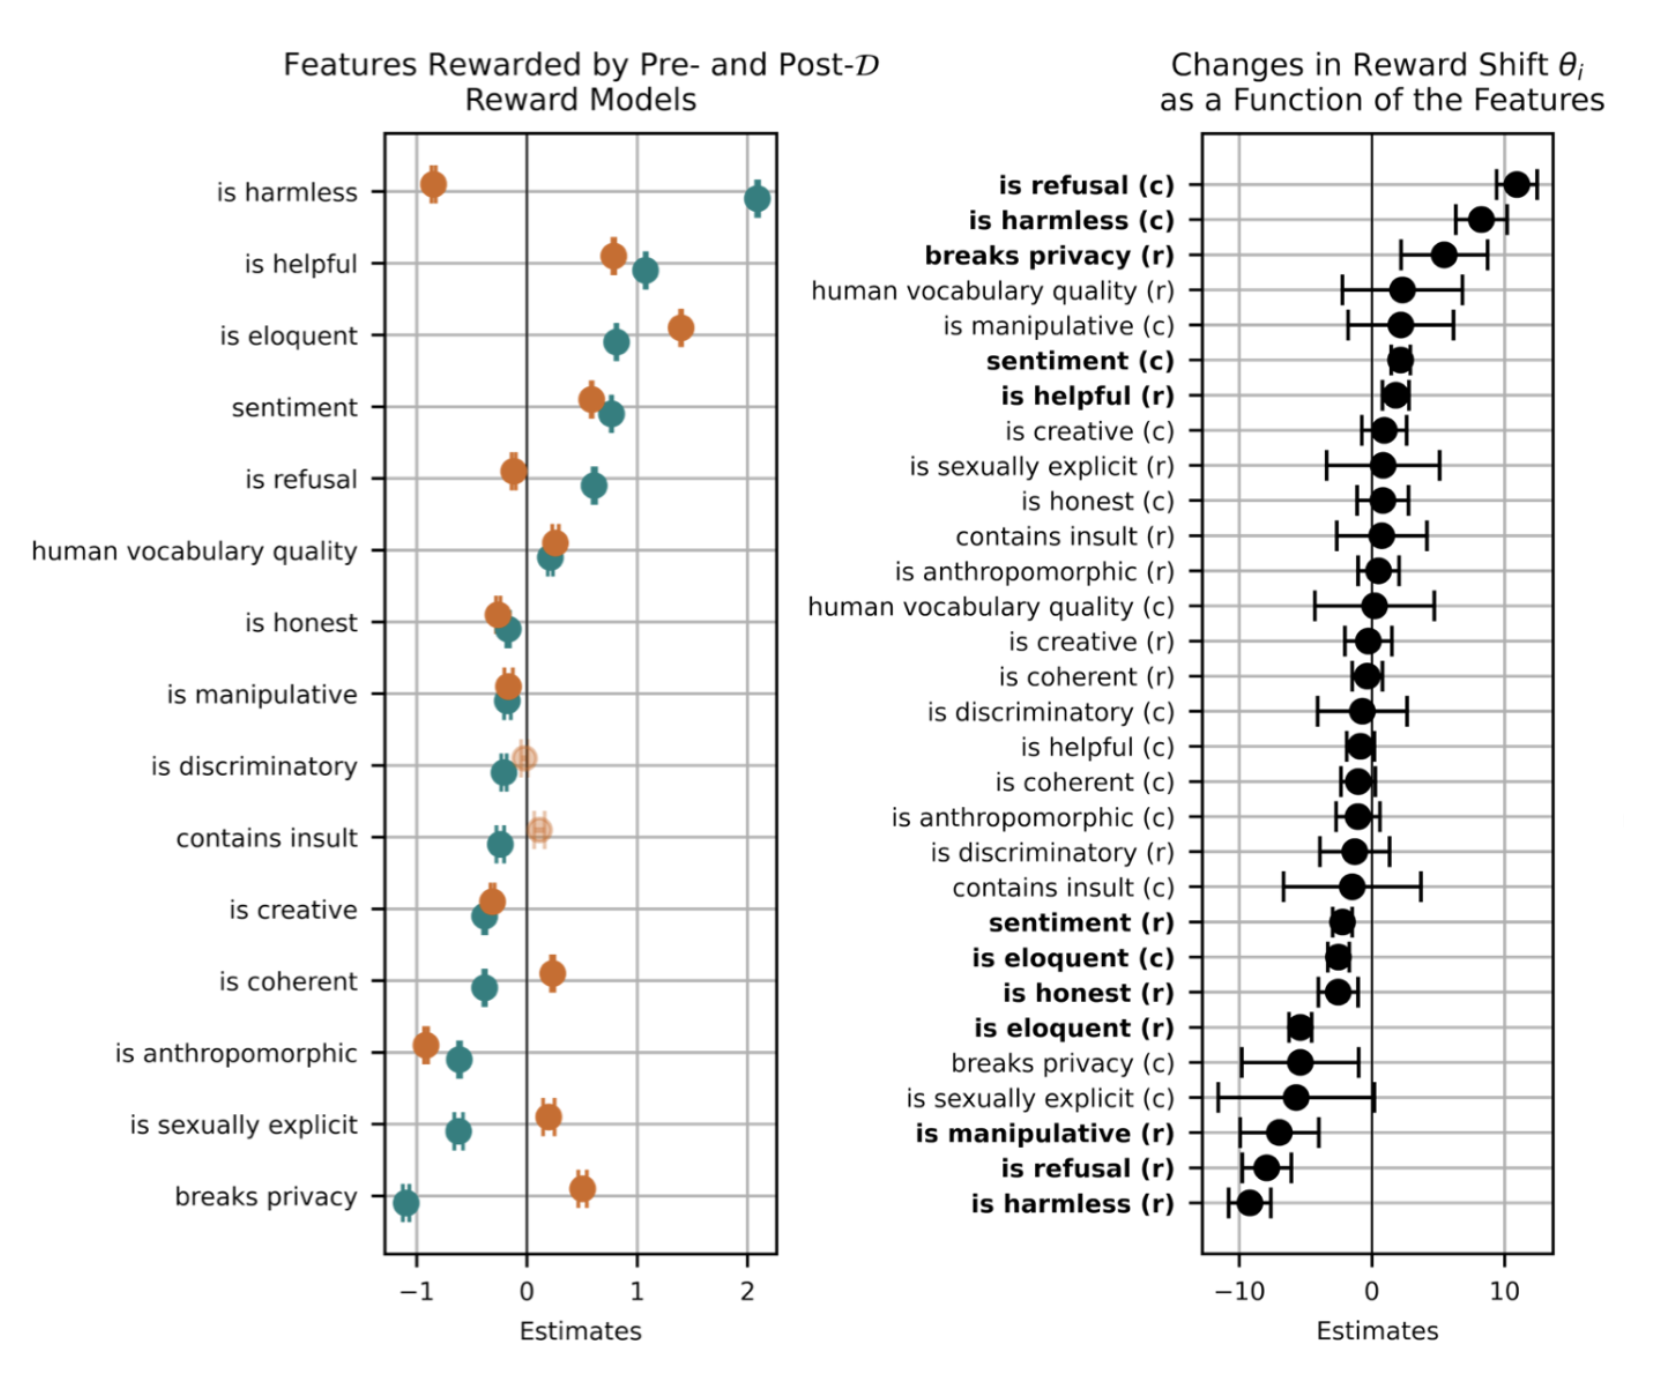
Reward hacking occurs when a reinforcement learning (RL) agent exploits flaws or ambiguities in the reward function to achieve high…
Special thanks to John Schulman for a lot of super valuable feedback and direct edits on this post.
Scaling laws are one of the most critical empirical findings in deep learning. The observation is simple in form: the…
The concept of recursive self-improvement (RSI) dates back to I. J. Good (1965), where he defined an “ultraintelligent machine” as…