

Adaptive Parallel Reasoning: The Next Paradigm in Efficient Inference Scaling
What if a reasoning model could decide for itself when to decompose and parallelize independent subtasks, how many concurrent threads…
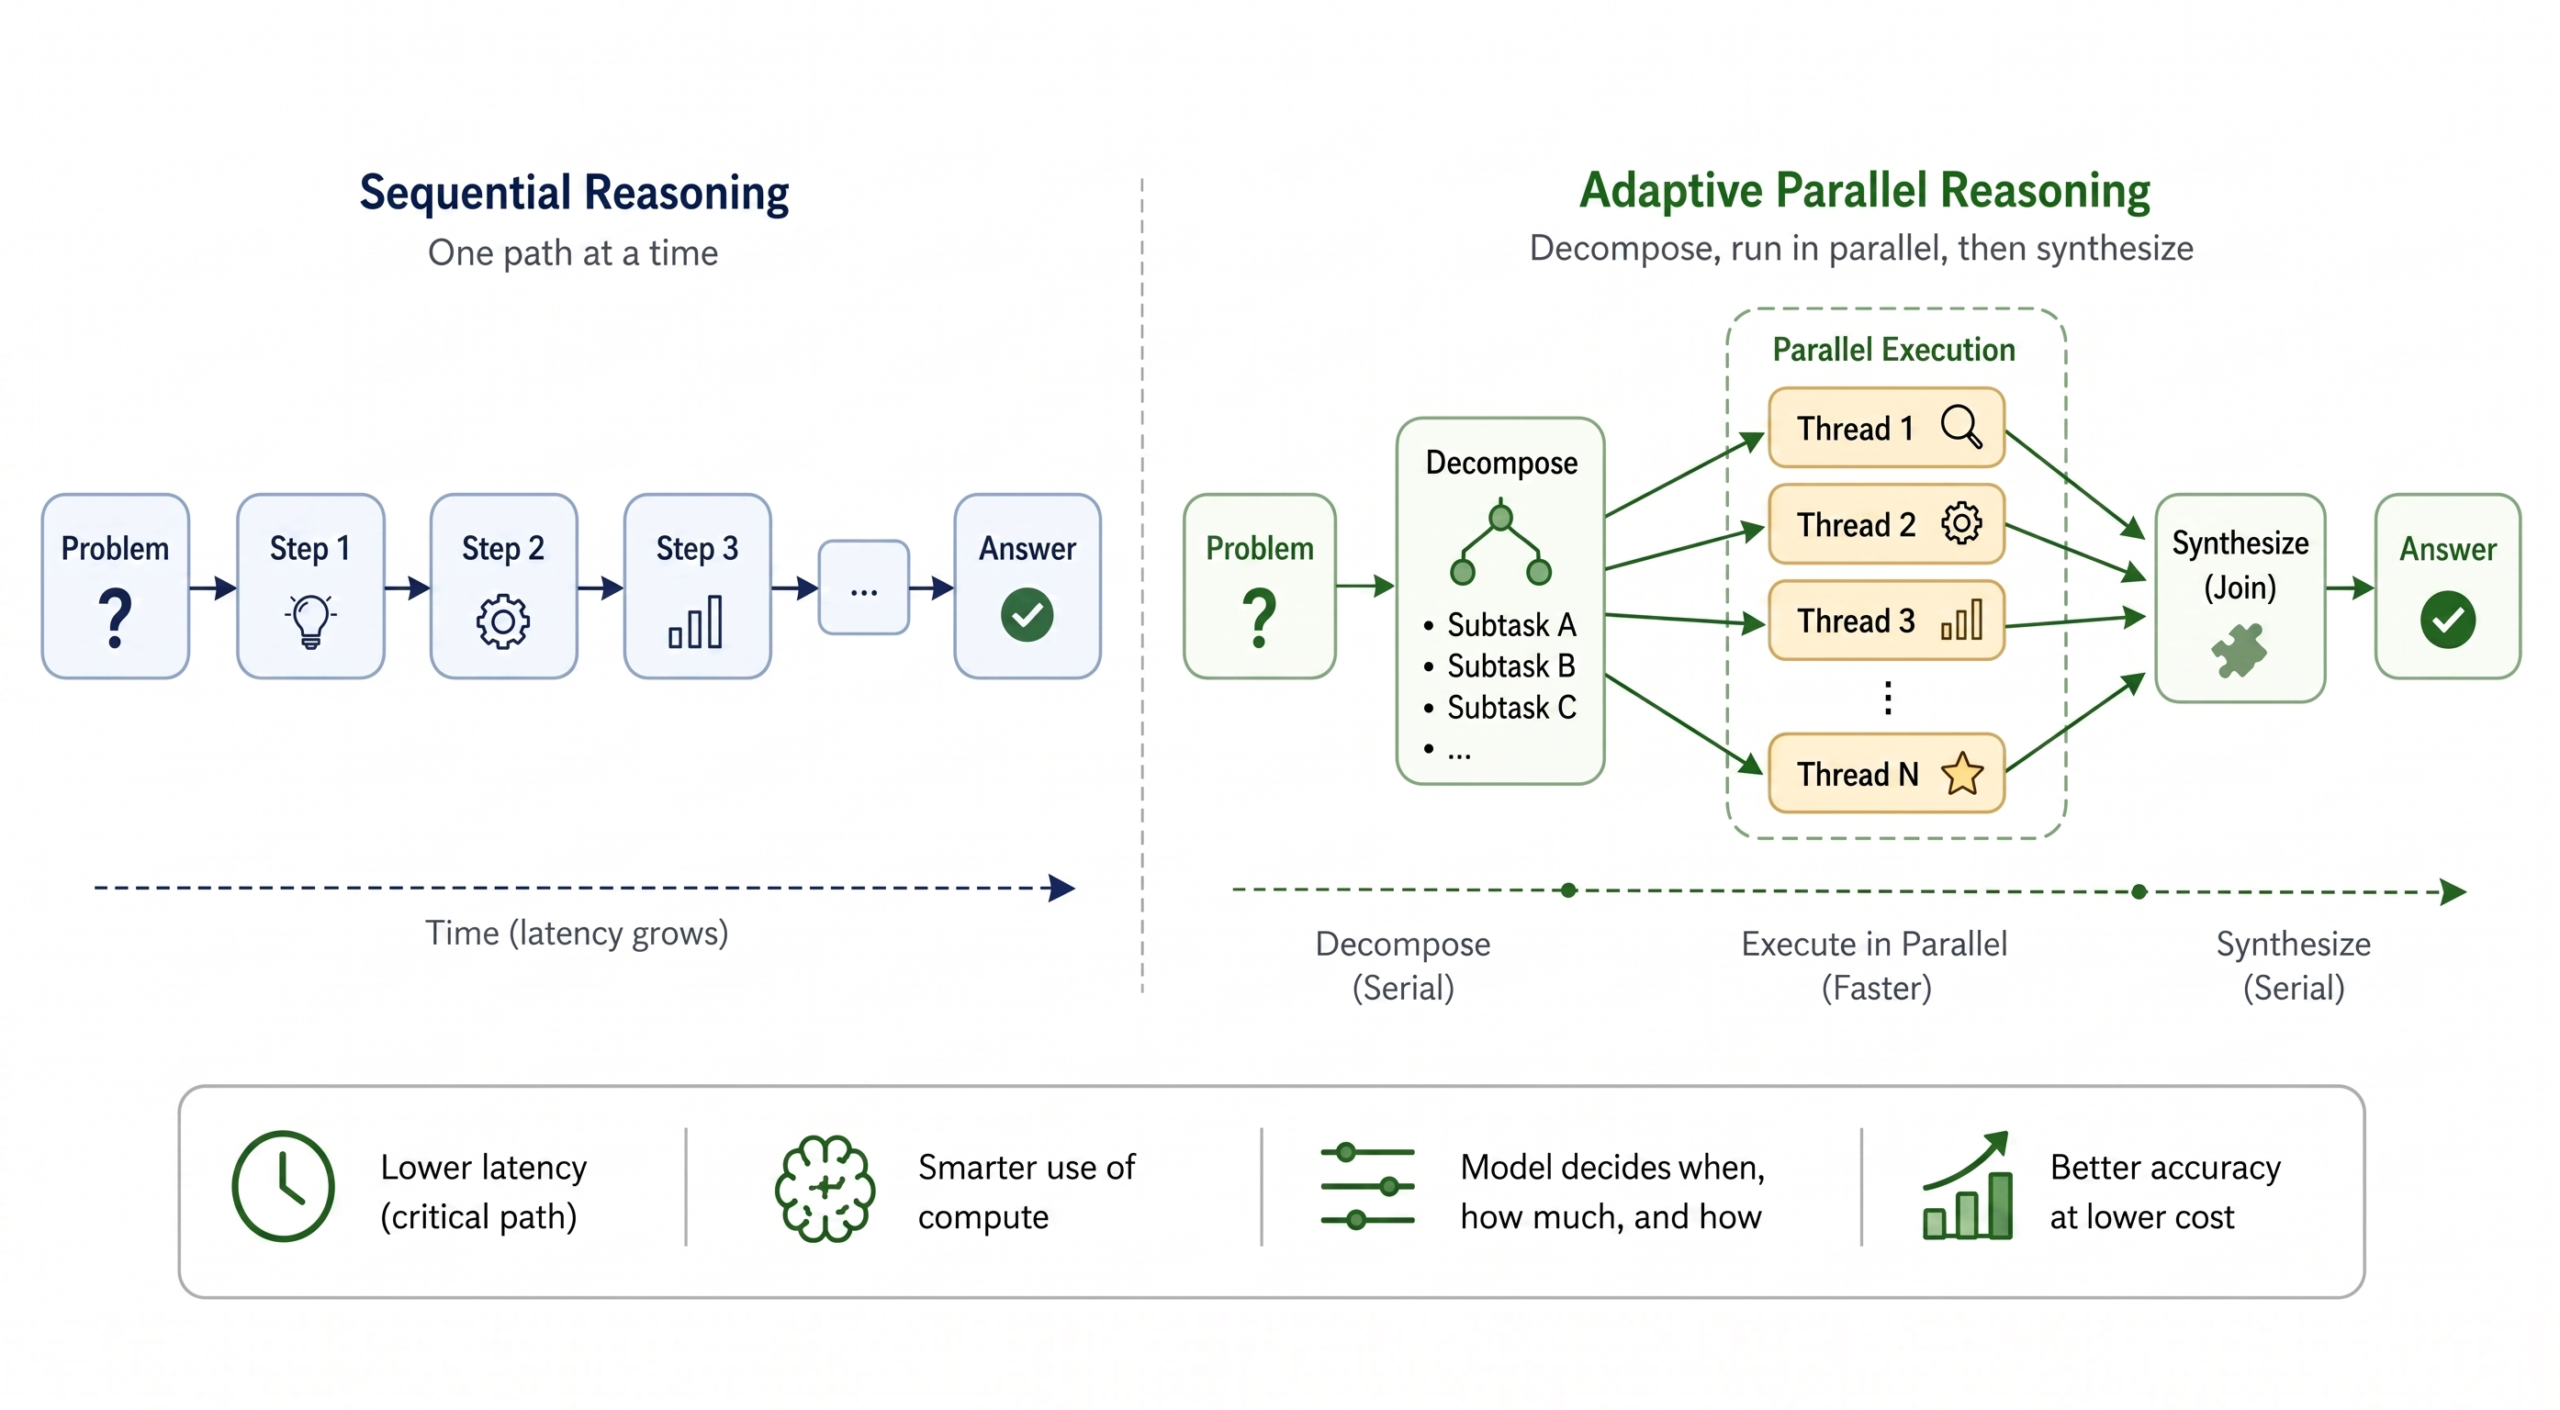
What if a reasoning model could decide for itself when to decompose and parallelize independent subtasks, how many concurrent threads…
Congratulations to the Berkeley Artificial Intelligence Research (BAIR) Lab class of 2026! This year, BAIR celebrates another remarkable group of…
... government of the people, by the people, for the people ... — Abraham Lincoln, Gettysburg Address (1863)
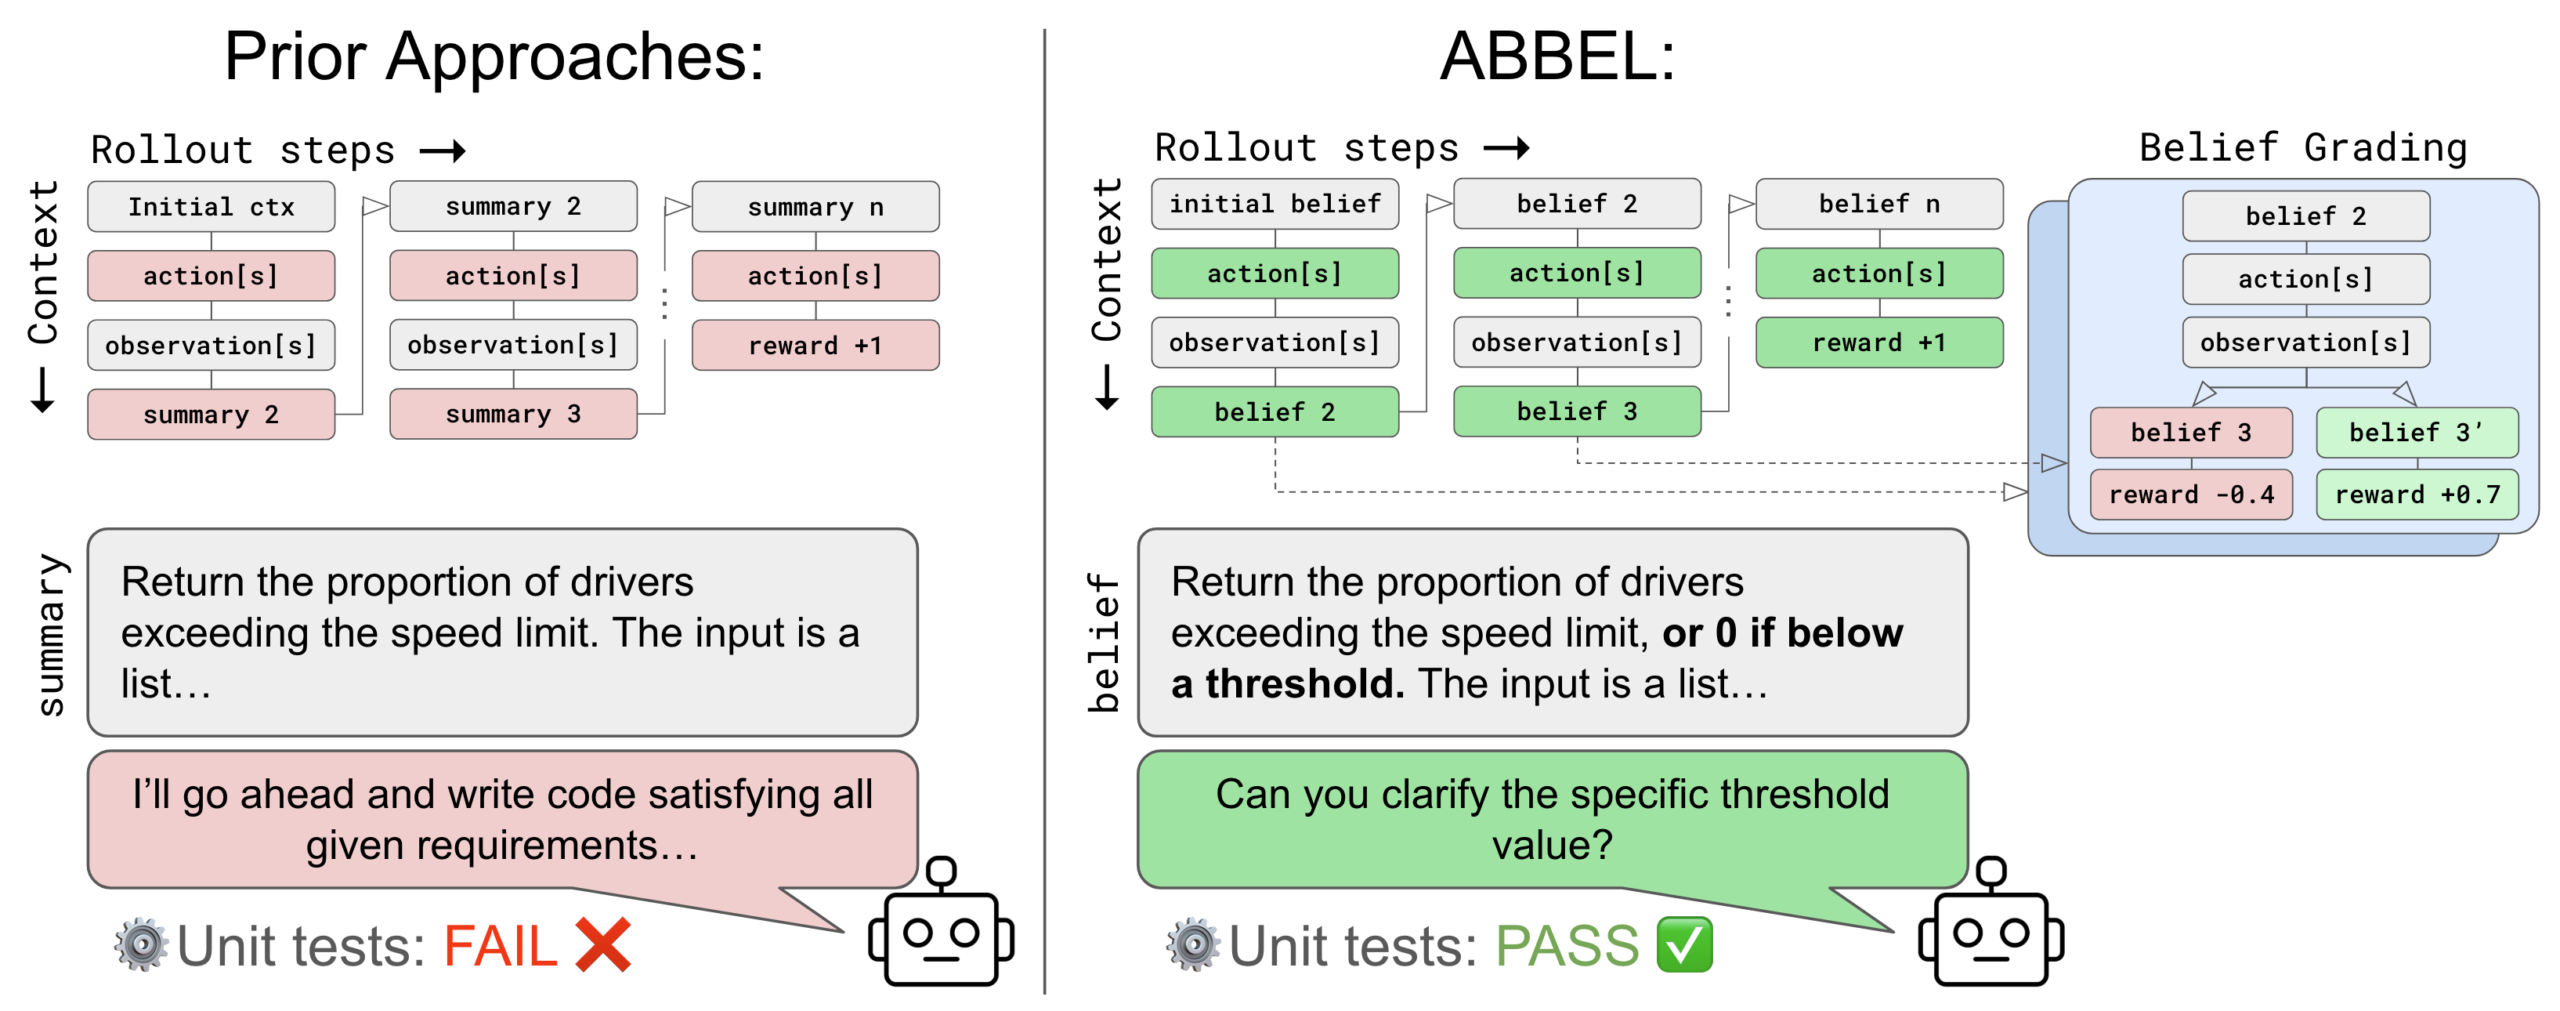
Overview of ABBEL compared to traditional recursive summarization. Beliefs replace the full interaction history as the agent’s working context, and…
Figure 1: CUDA-to-MLX optimization translation map. CUDA optimization knowledge can be translated into architecture-native MLX strategies rather than copied instruction-for-instruction.
Maximum inner product search (MIPS) sits at the core of recommendation systems, search, and retrieval-augmented generation (RAG). Given a query…
Genie 4: our new world model unlocking unprecedented realism in real-time simulation.
Gemini 4 Carbon is our strongest model with state-of-the-art cybersecurity and long horizon capabilities.
Google DeepMind and UK government work together to reduce planning assessment times
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.