


Update August 30, 2024: We've released updated versions of Command R and R+.
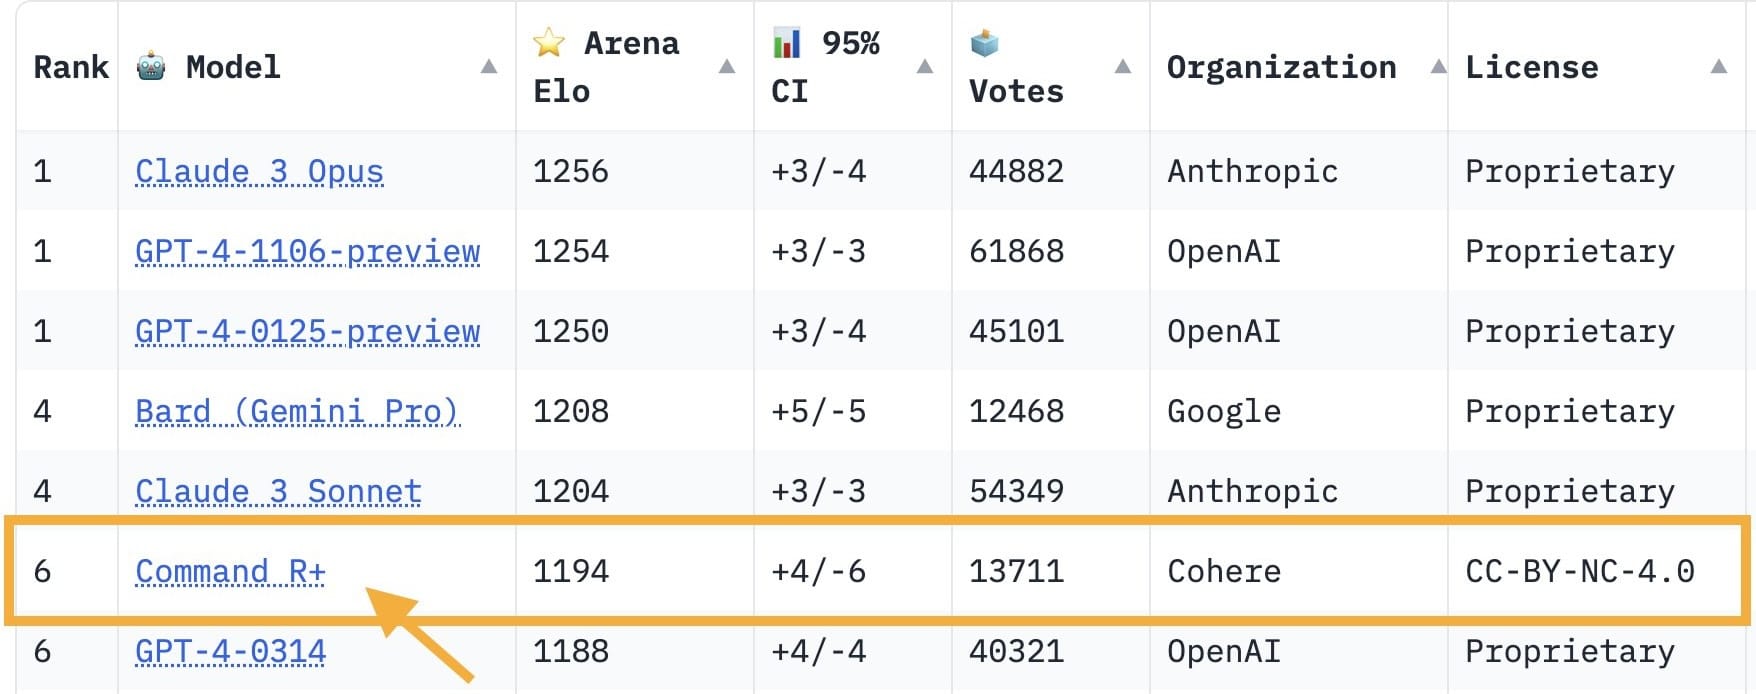
This post is an update on what I’ve been up to since I joined Cohere. I’ve had fun contributing to the launch of Command R and R+, the latest Cohere models. Command R+ is ranked as the top open-weights model on Chatbot Arena, even outperforming some versions of GPT-4. Why is this exciting?
Let’s talk about why we should care about Chatbot Arena rankings in the first place. I’ve written in the past about challenges in NLP benchmarking. Pre-LLM benchmarks such as SuperGLUE mostly consist of classification tasks and no longer provide sufficient signal to differentiate the latest generation of LLMs. More recent benchmarks such as MT-Bench consist of small samples of open-ended questions and rely on LLMs as evaluators, which have their own sets of biases.
MMLU, one of the most widely used benchmarks consisting of 14k multiple-choice questions sourced from public sources covering 57 domains has been featured prominently in GPT-4, Claude 3, and Mistral Large posts. The data is not without errors, however, and given its release in 2020, training data of recent models is likely at least partially contaminated.
Source: Sebastian Ruder — Read the full article on the original site ↗