


The challenge of running LLM applications in production is that failures are silent, costs are unpredictable, and security vulnerabilities are hard to detect until it’s too late.
Download this Datadog eBook for practical strategies to monitor, debug, and secure your LLM application workflows end-to-end. You’ll get 4 key insights into how to overcome the challenges of deploying LLMs at scale — from tracing multi-step chain executions and detecting prompt injection attacks to tracking token costs and evaluating output quality in real time.
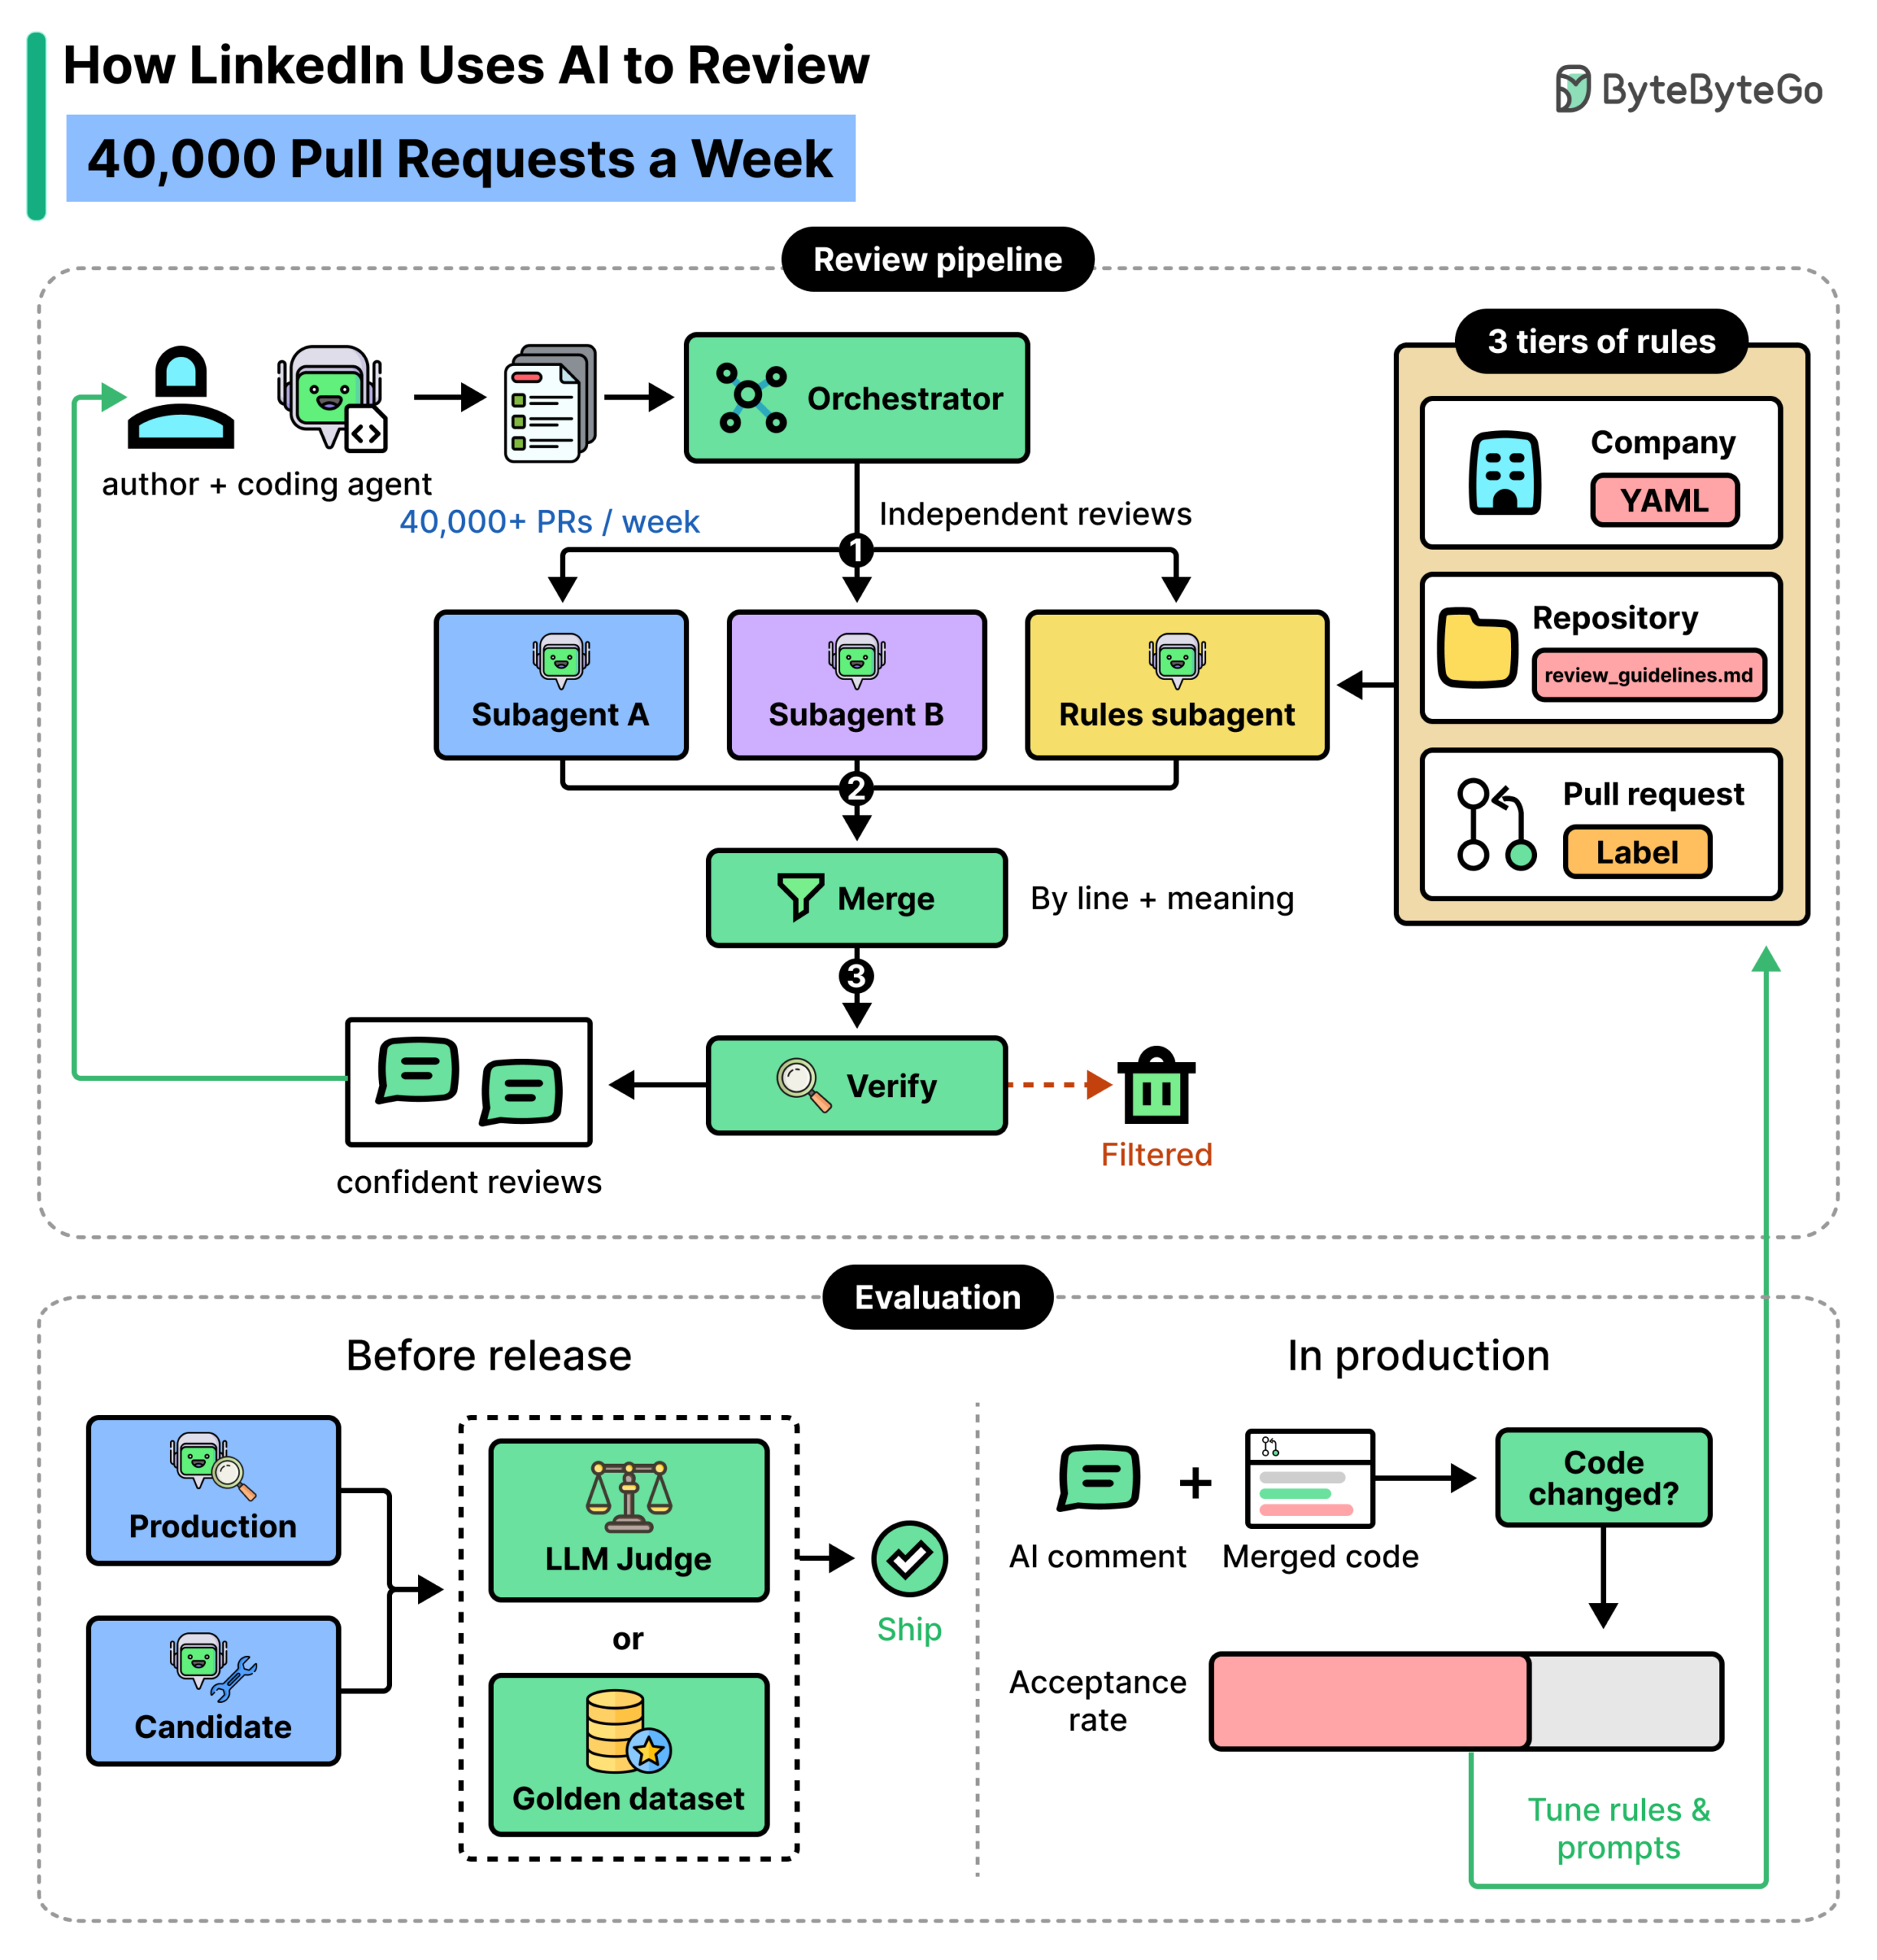
LinkedIn has more than 10,000 active code repositories, with tens of thousands of pull requests (PRs) being opened each week [1]. As coding agents write more of that code, the slow part of shipping software has moved from writing code to reviewing it.
To overcome the code review bottleneck, LinkedIn built its own AI reviewer. In a typical week, this in-house reviewer covers more than 40,000 PRs, and most of its reviews are posted before the first human reviewer even opens the PR [1].
Source: ByteByteGo (system design interviews) — Read the full article on the original site ↗