


India's Most Futuristic AI Conference Is Back – Bigger, Sharper, Bolder
I started writing this blog when Kimi K3 was still Moonshot’s flagship. Then, on 24th October 2026, Kimi K3.1 Pro dropped, right in the middle of my writing, hehe. The good news: K3.1 Pro is built on the same K3 base model with much more post-training on top, so everything we study here still applies. Moonshot compares it head-to-head with Claude Opus 5.5 and GPT-6 Astra, and on the independent Artificial Analysis index it sits just three points behind Opus 5.5.
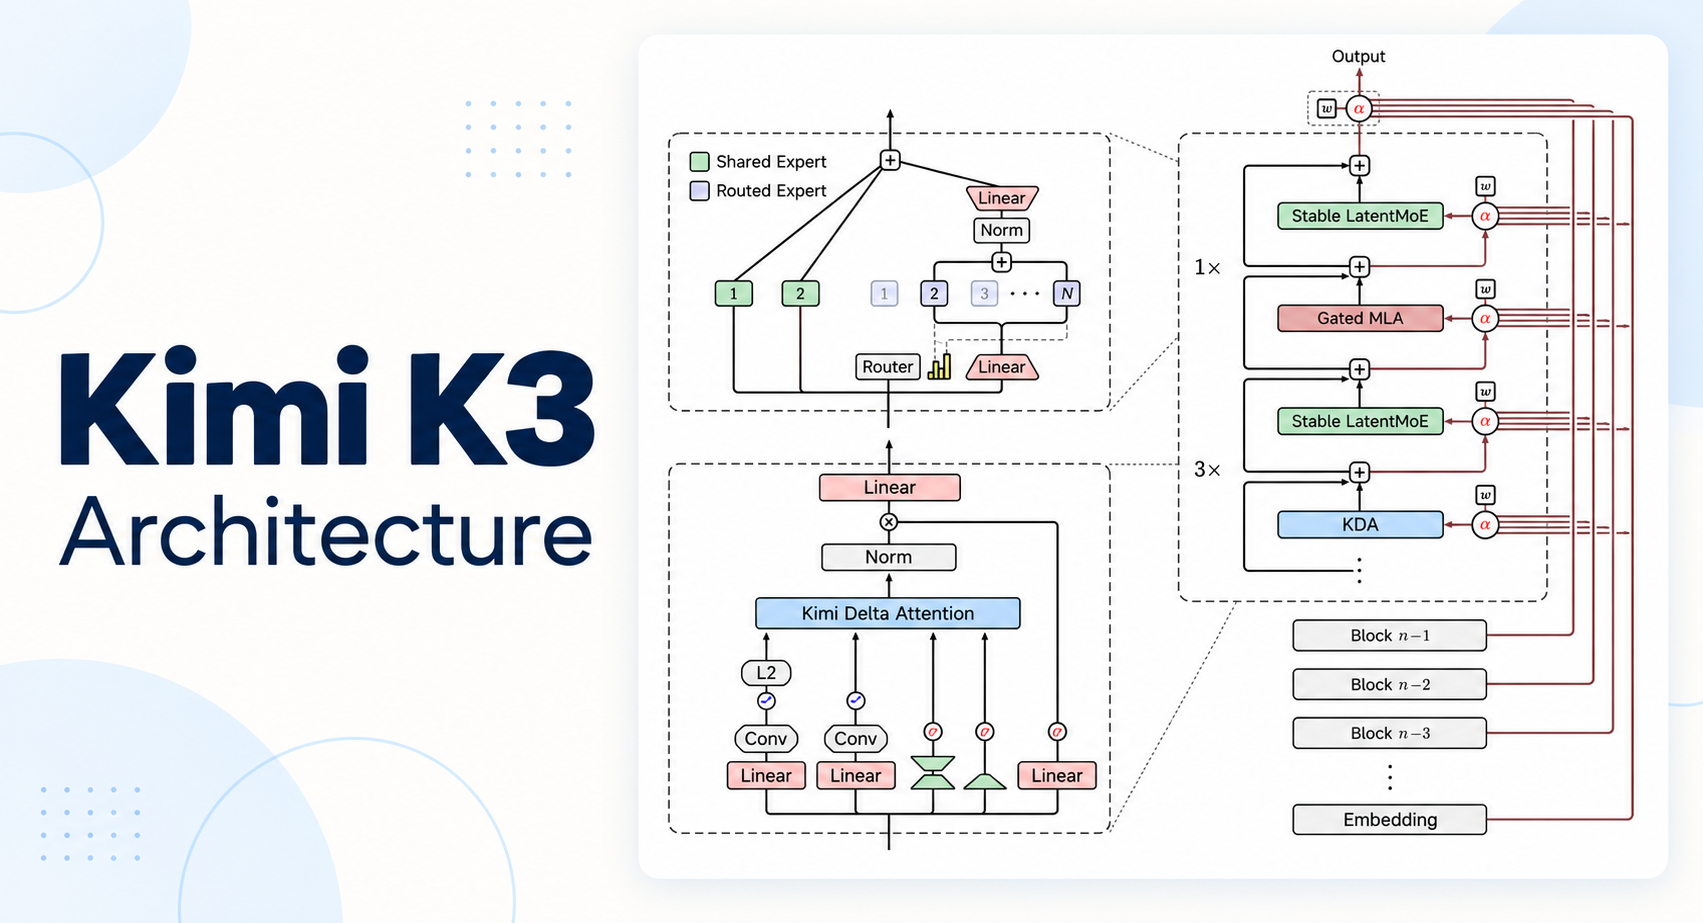
K3 itself is worth understanding. It is one of the largest open models, with 2.8T parameters and 896 routed experts, yet it cost over 3x less per token than Claude Fable 5 at list prices. That efficiency comes from a stack of research ideas, including linear attention, mixture of experts and attention residuals, each built to keep costs low without losing quality.
The model is so large that even at 4-bit precision, its weights alone take about 1.4 TB, far more than a single GPU can hold. Its experts are spread across many GPUs, so a single token can hop between several of them before a reply is written.
Source: Analytics Vidhya — Read the full article on the original site ↗