


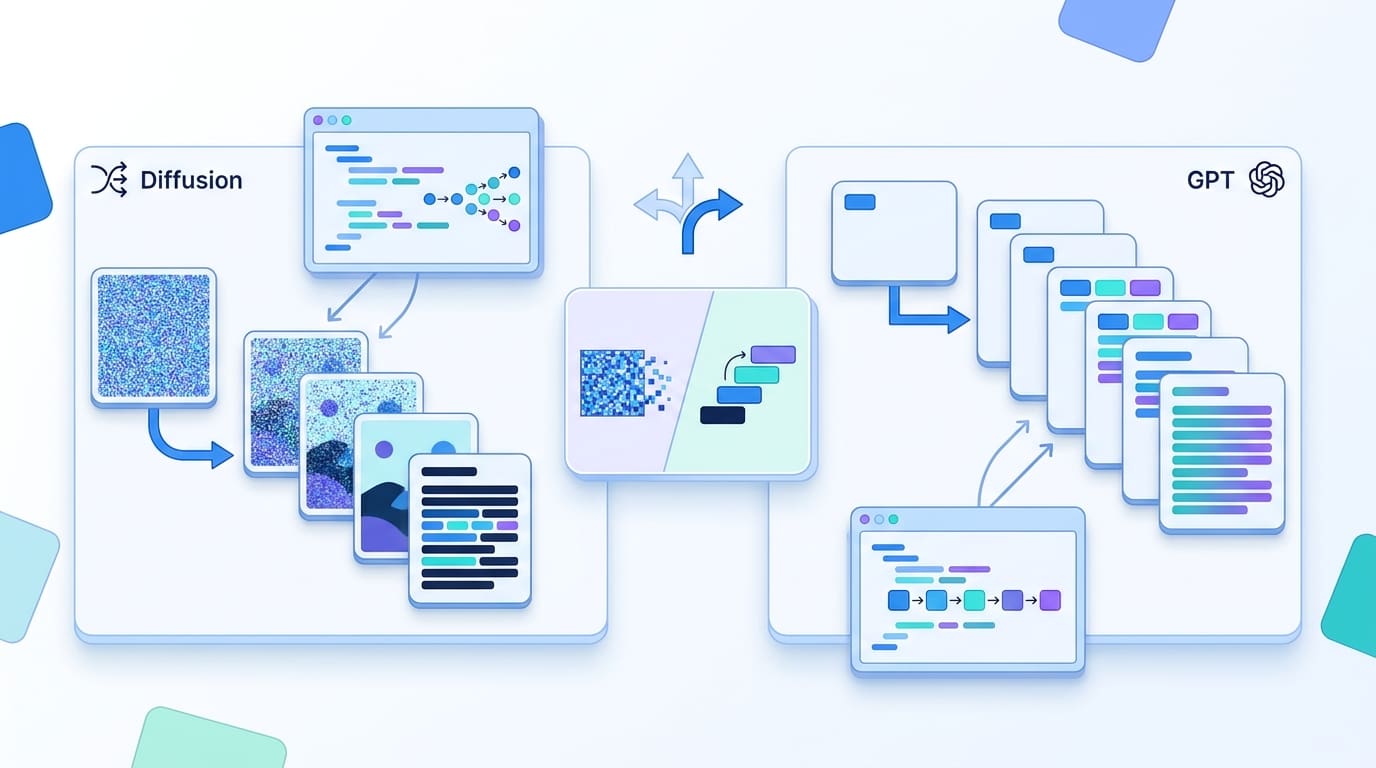
In this article, you will learn how diffusion language models generate text by iteratively refining a masked sequence, and how this differs from the token-by-token generation of GPT-style models.
Diffusion itself is not a new idea. It is well known from the image generators that transform random noise into meaningful images, and this work was presented in the Denoising Diffusion Probabilistic Models paper. However, the problem is that this idea of starting with something noisy and then refining it is easier to understand with images, which consist of continuous values. Applying this idea to text is usually hard, as text is made of discrete token IDs, and adding a little Gaussian noise to a token ID does not produce a meaningful nearby word.
However, recent work, including LLaDA, Mercury, and Gemini Diffusion in 2025, and then Google’s DiffusionGemma in 2026, has drawn the community’s attention to diffusion models because of their faster inference. A traditional large language model (LLM) predicts the next token, adds it to the sequence, and then repeats this. But diffusion models predict multiple positions simultaneously and refine their predictions before producing an answer. This raises a major research question in the community:
I will not pass a verdict on it. Also, this topic is kind of complex, so I don’t expect you to understand it fully, and I have kept the math as minimal as possible. But I do want you to take away the intuition of what is happening. In this article, we will study:
Source: Machine Learning Mastery — Read the full article on the original site ↗