


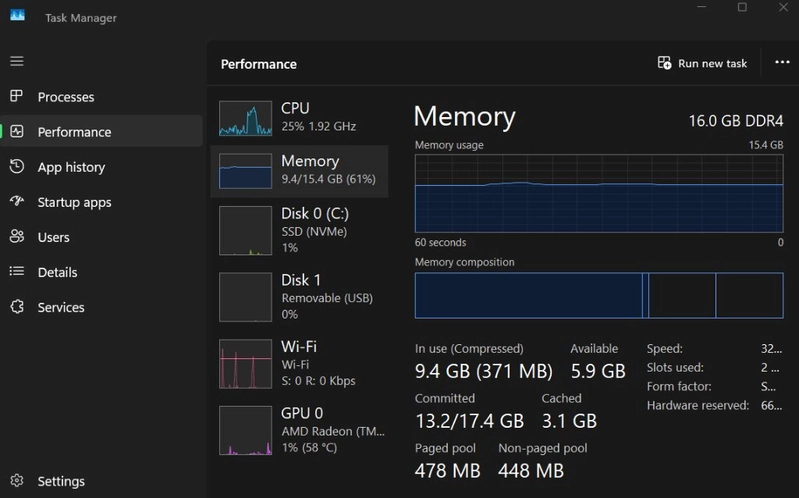
Author: myne (mvyne06) Hardware: AMD Ryzen 5 5625U (6 Cores / 12 Threads), 16 GB DDR4-3200 RAM, Integrated AMD Radeon Graphics Repository: github.com/mvyne06/edge-agent-bottlenecks Tooling & Attribution: Project narrative, hardware setup, and testing by myne; terminal log profiling, architectural diagrams, and benchmark formatting assisted by Google Antigravity.
My goal was to run an SLM locally and connect it to a cloud LLM environment (Google Antigravity). However, this didn't end up working as I expected.
I originally tried running Qwen 3.5-4B as it scored the highest on benchmarks and seemed the best at the time. llama.cpp was set up using Vulkan so that the model ran on the iGPU to be more efficient. In this case, the iGPU and CPU share the same bus and RAM, but my reasoning was that the iGPU should be more efficient since it's better at matrix math.
The performance was really bad; it took really long for the model to do anything, even simple tasks. I tried switching to the CPU, but that didn't do much. So I caved and switched to an even smaller model (Qwen 3.5-2B). The performance boost was marginal.
Source: DEV - machine learning — Read the full article on the original site ↗