

Reward Hacking in Reinforcement Learning
Reward hacking occurs when a reinforcement learning (RL) agent exploits flaws or ambiguities in the reward function to achieve high…
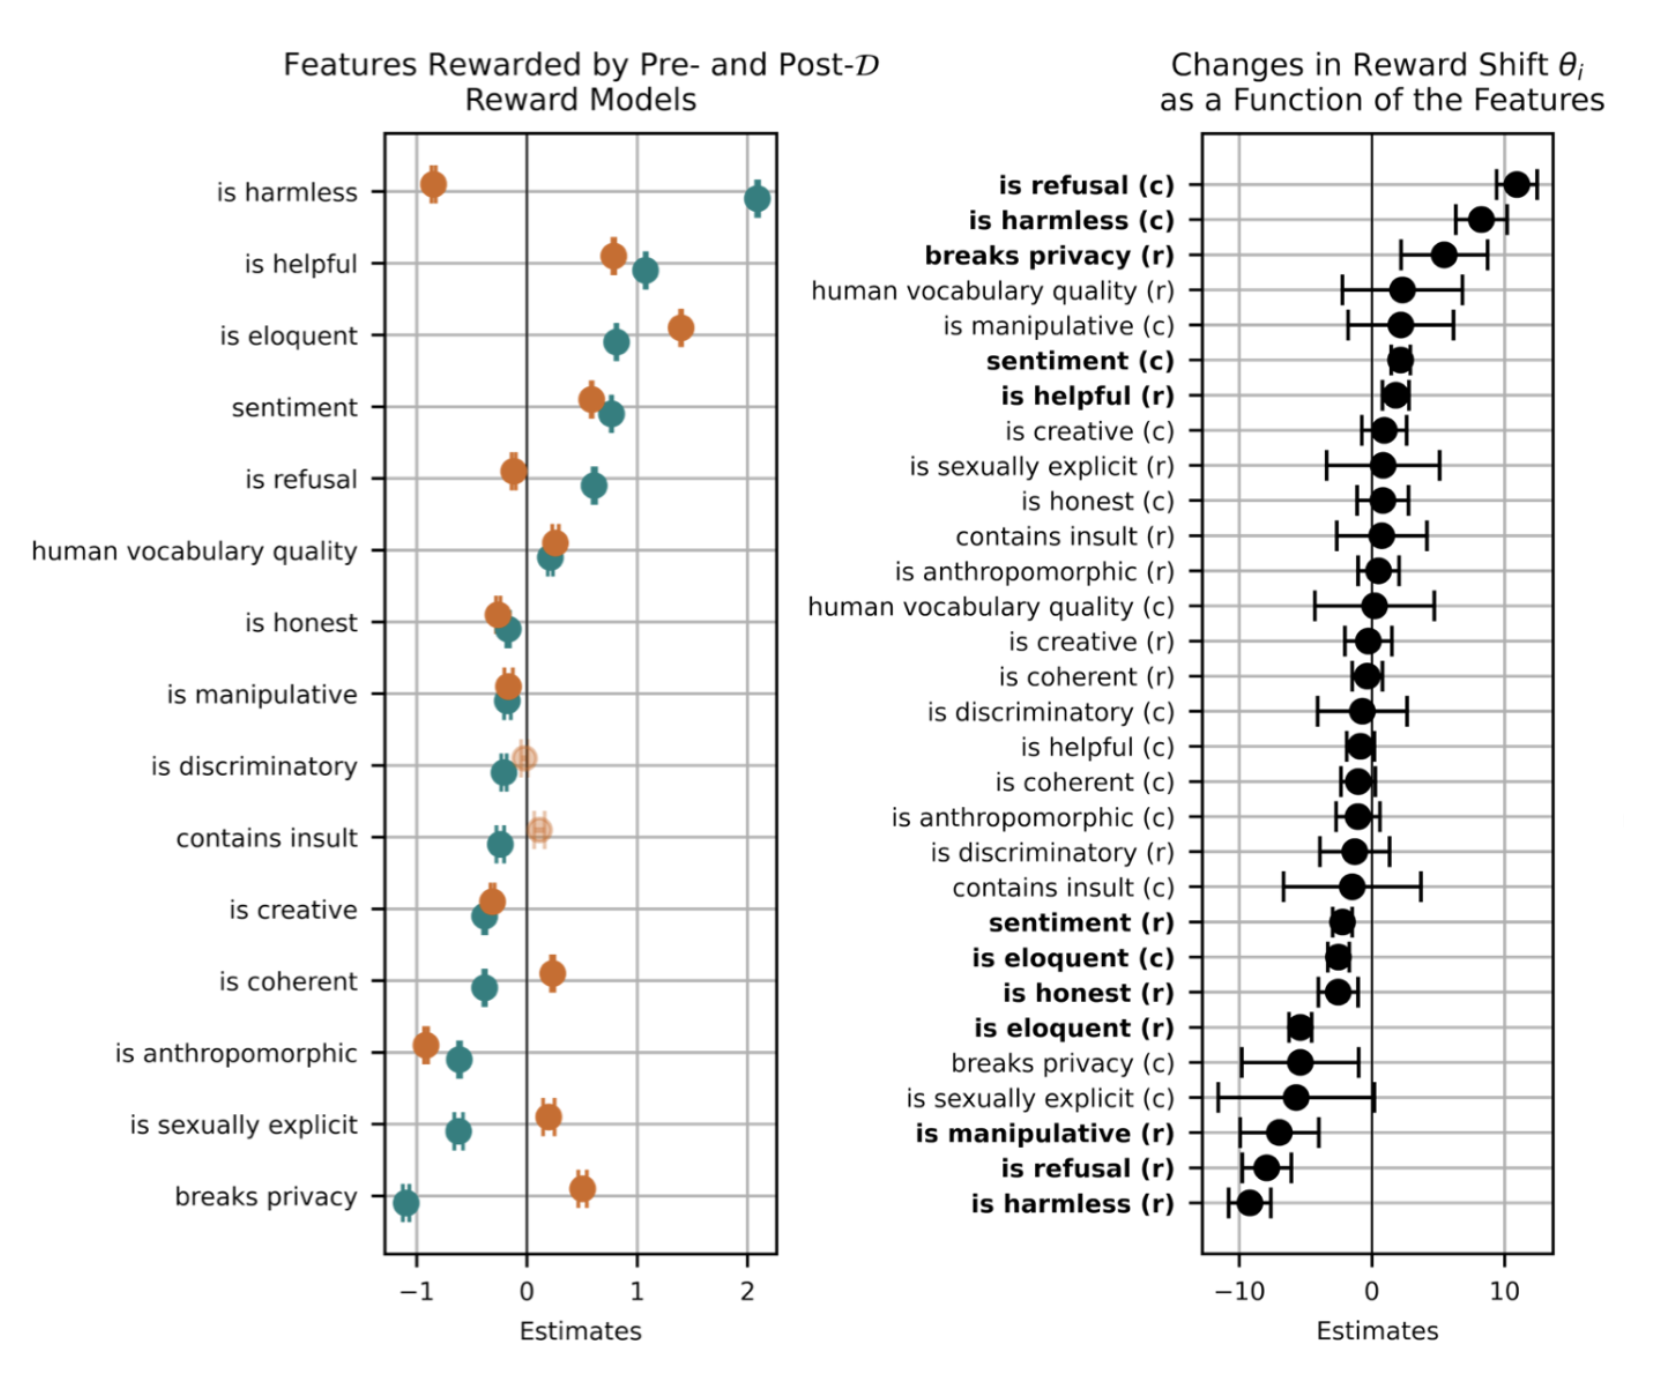
Reward hacking occurs when a reinforcement learning (RL) agent exploits flaws or ambiguities in the reward function to achieve high…
Special thanks to John Schulman for a lot of super valuable feedback and direct edits on this post.
Scaling laws are one of the most critical empirical findings in deep learning. The observation is simple in form: the…
The concept of recursive self-improvement (RSI) dates back to I. J. Good (1965), where he defined an “ultraintelligent machine” as…
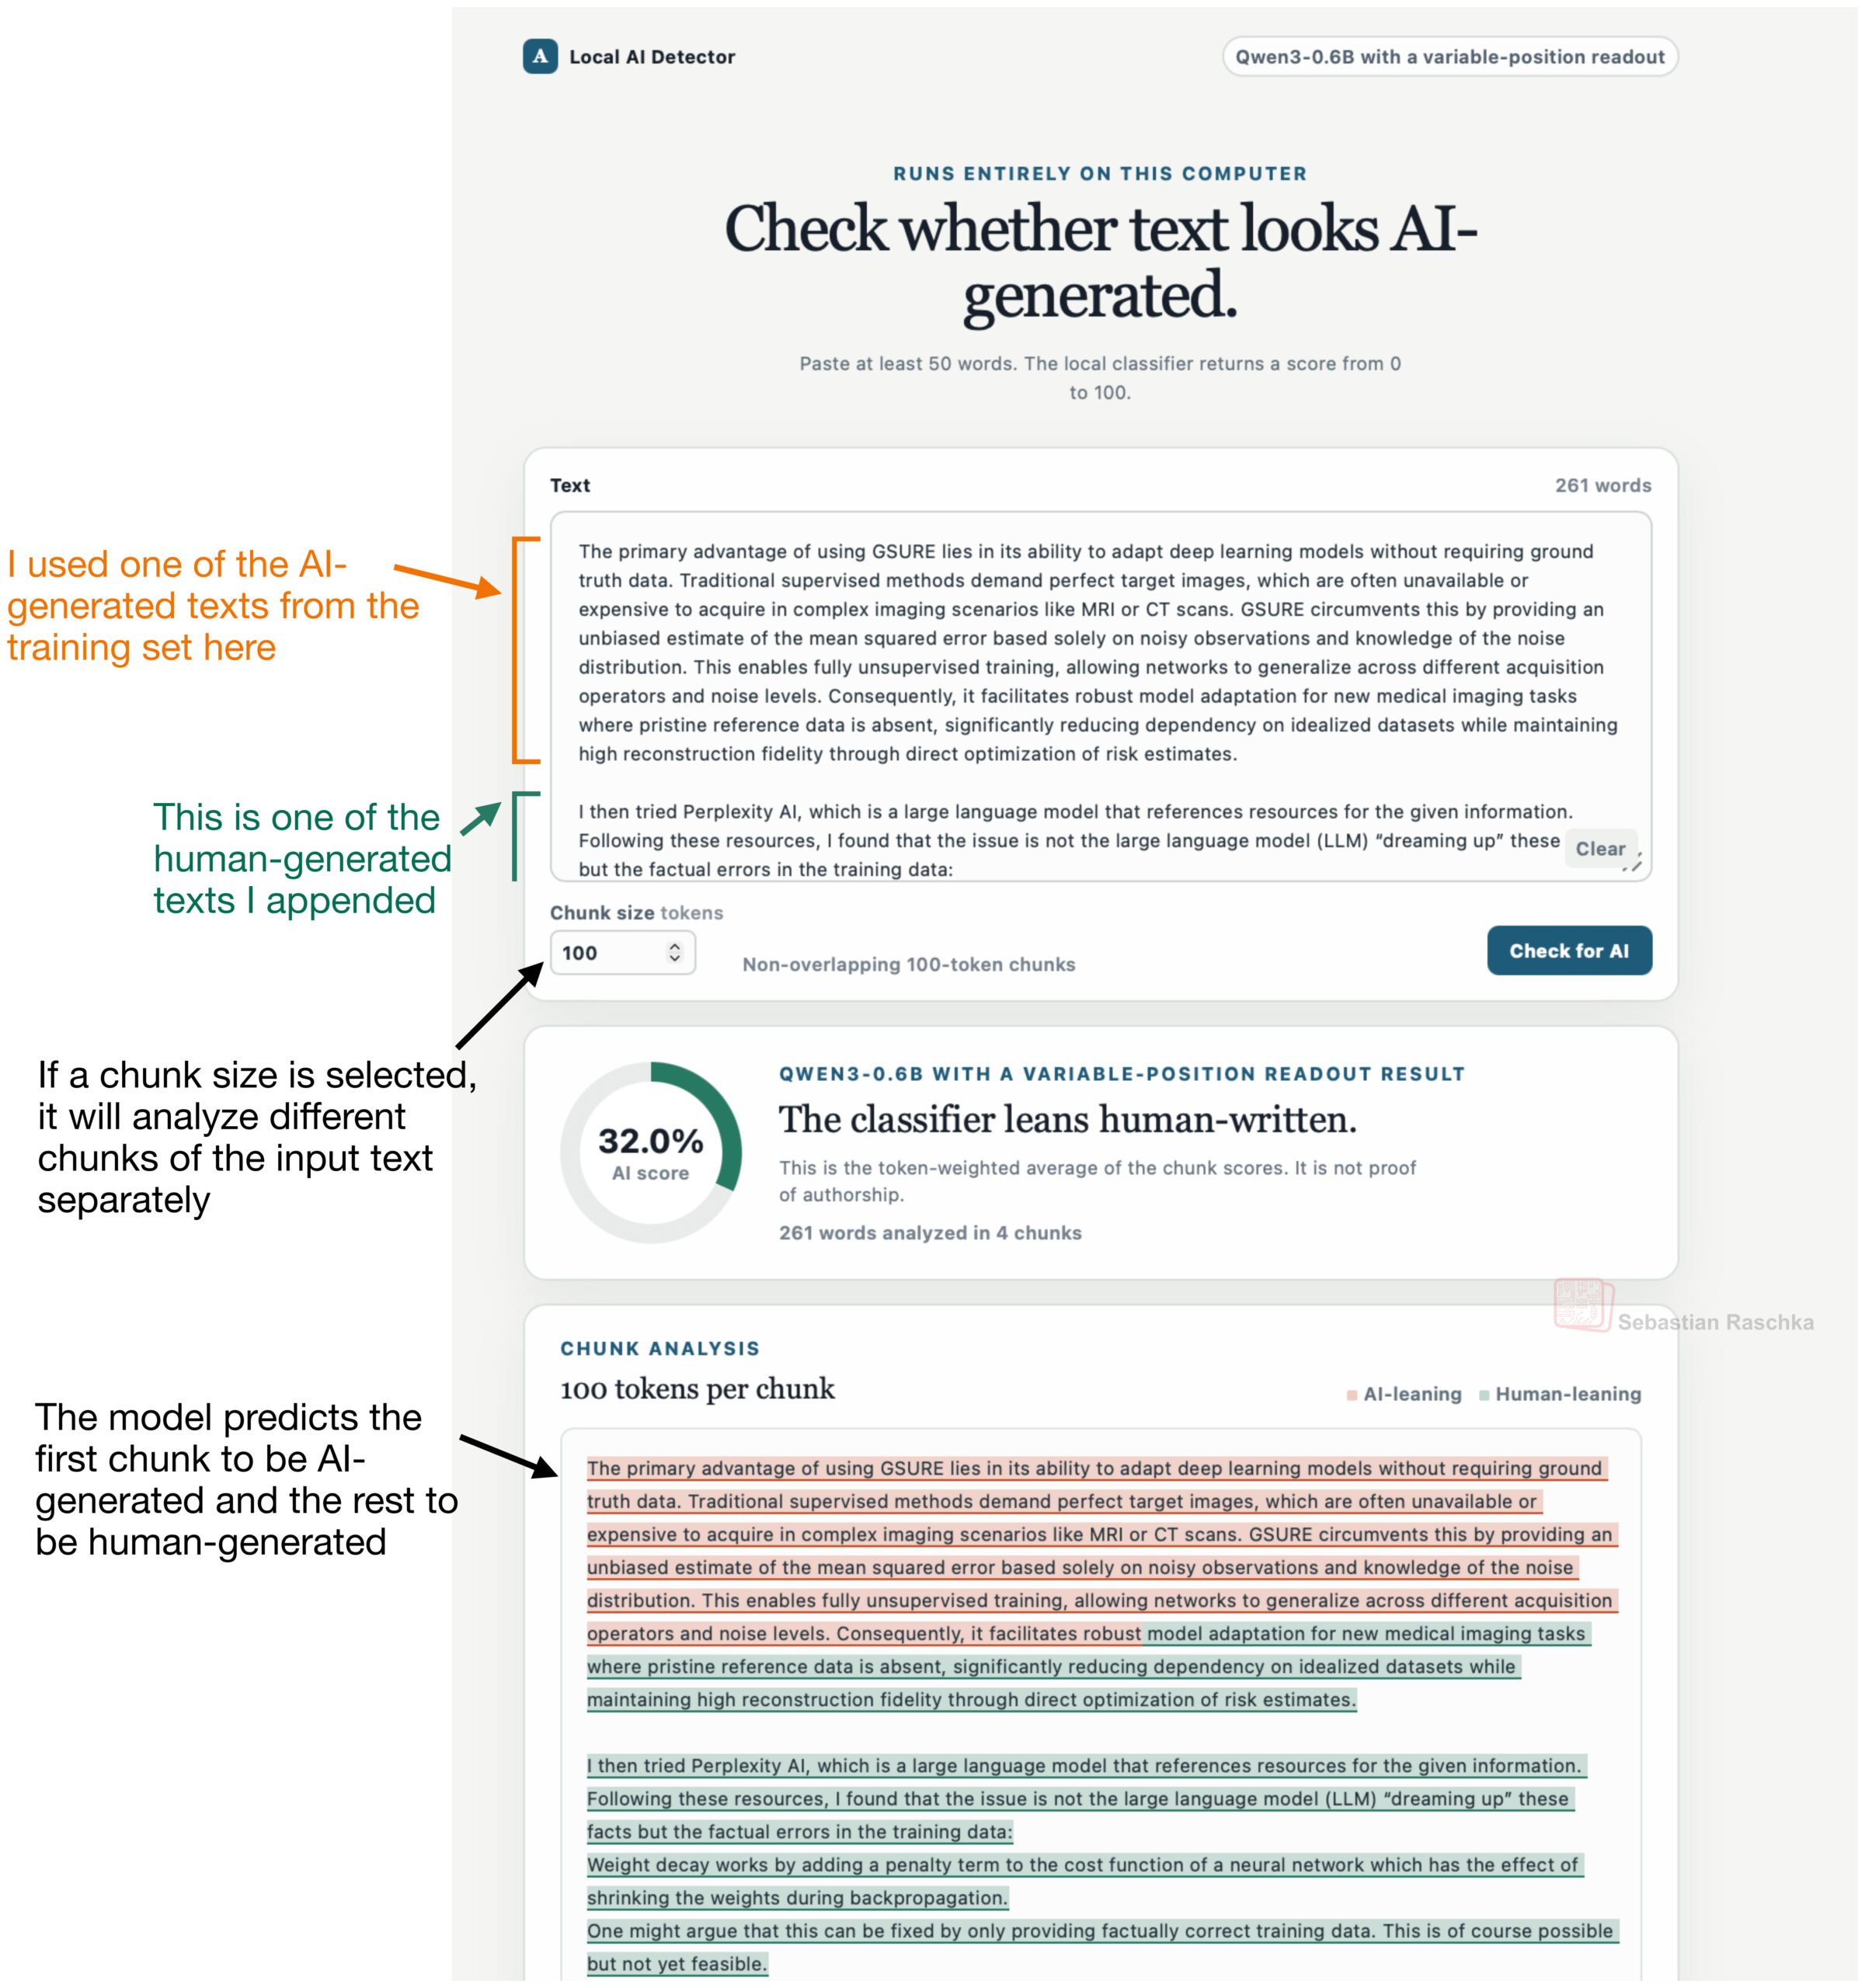
Substack recently launched its AI detector feature in the UI, which is super interesting.
I recently posted a Substack note about Claude’s new watermarking process and implementation. Since it’s such a popular topic and…
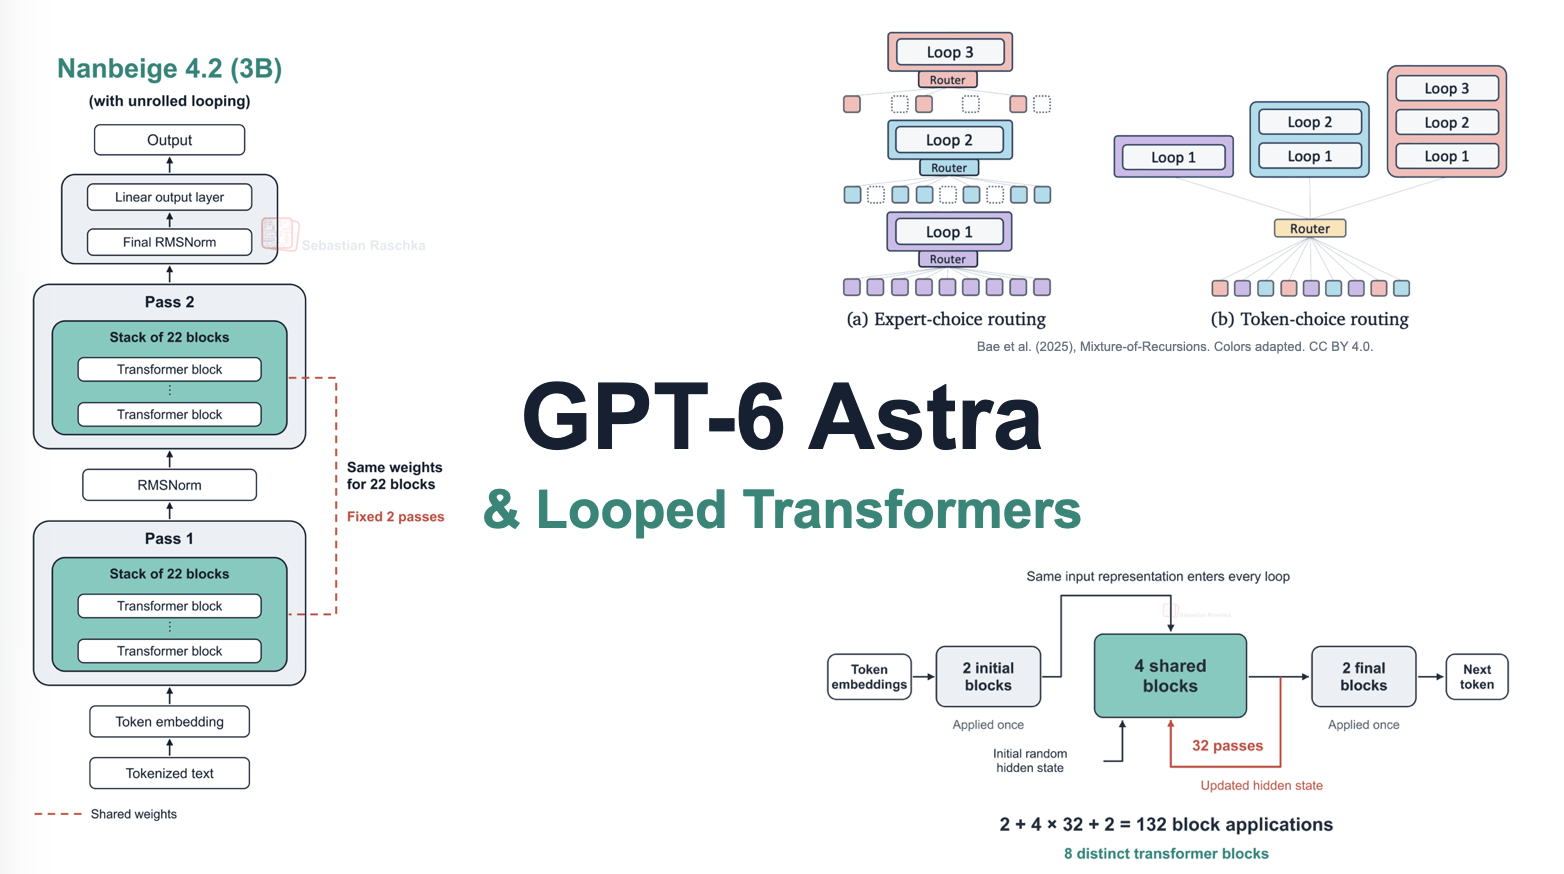
A lot has happened in the last few weeks. I am sure that OpenAI’s GPT-6 Astra is top of mind…
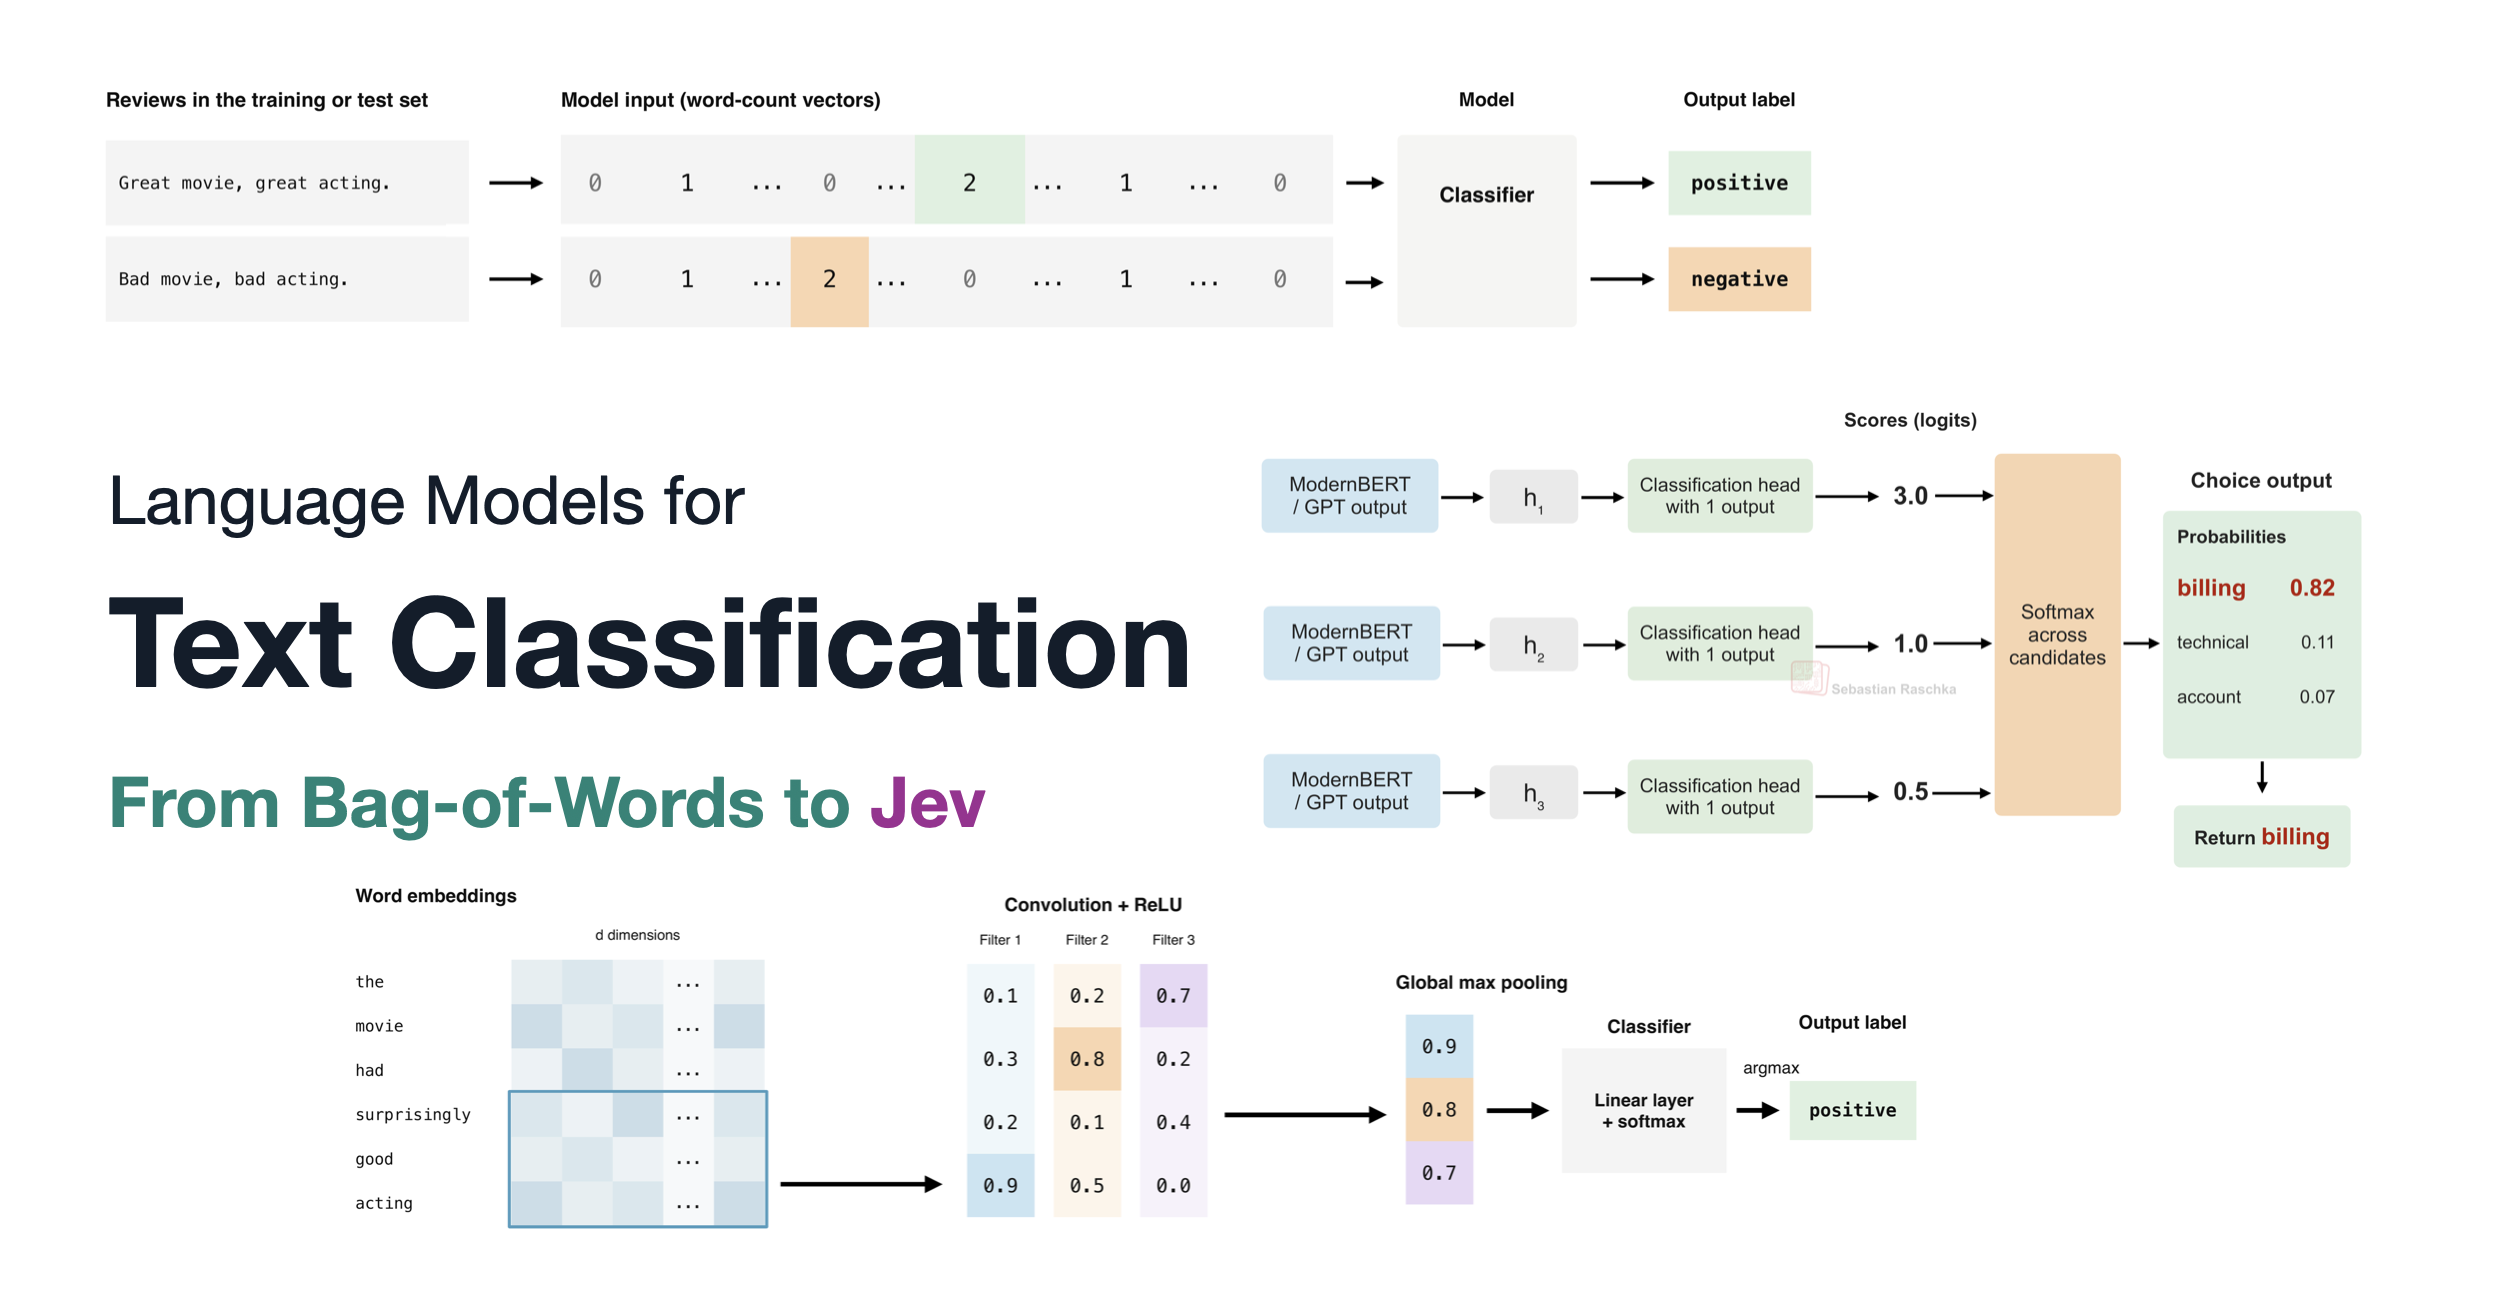
The recently released Jev AI model has been quite a cultural phenomenon in technical communities in the past 2 weeks.
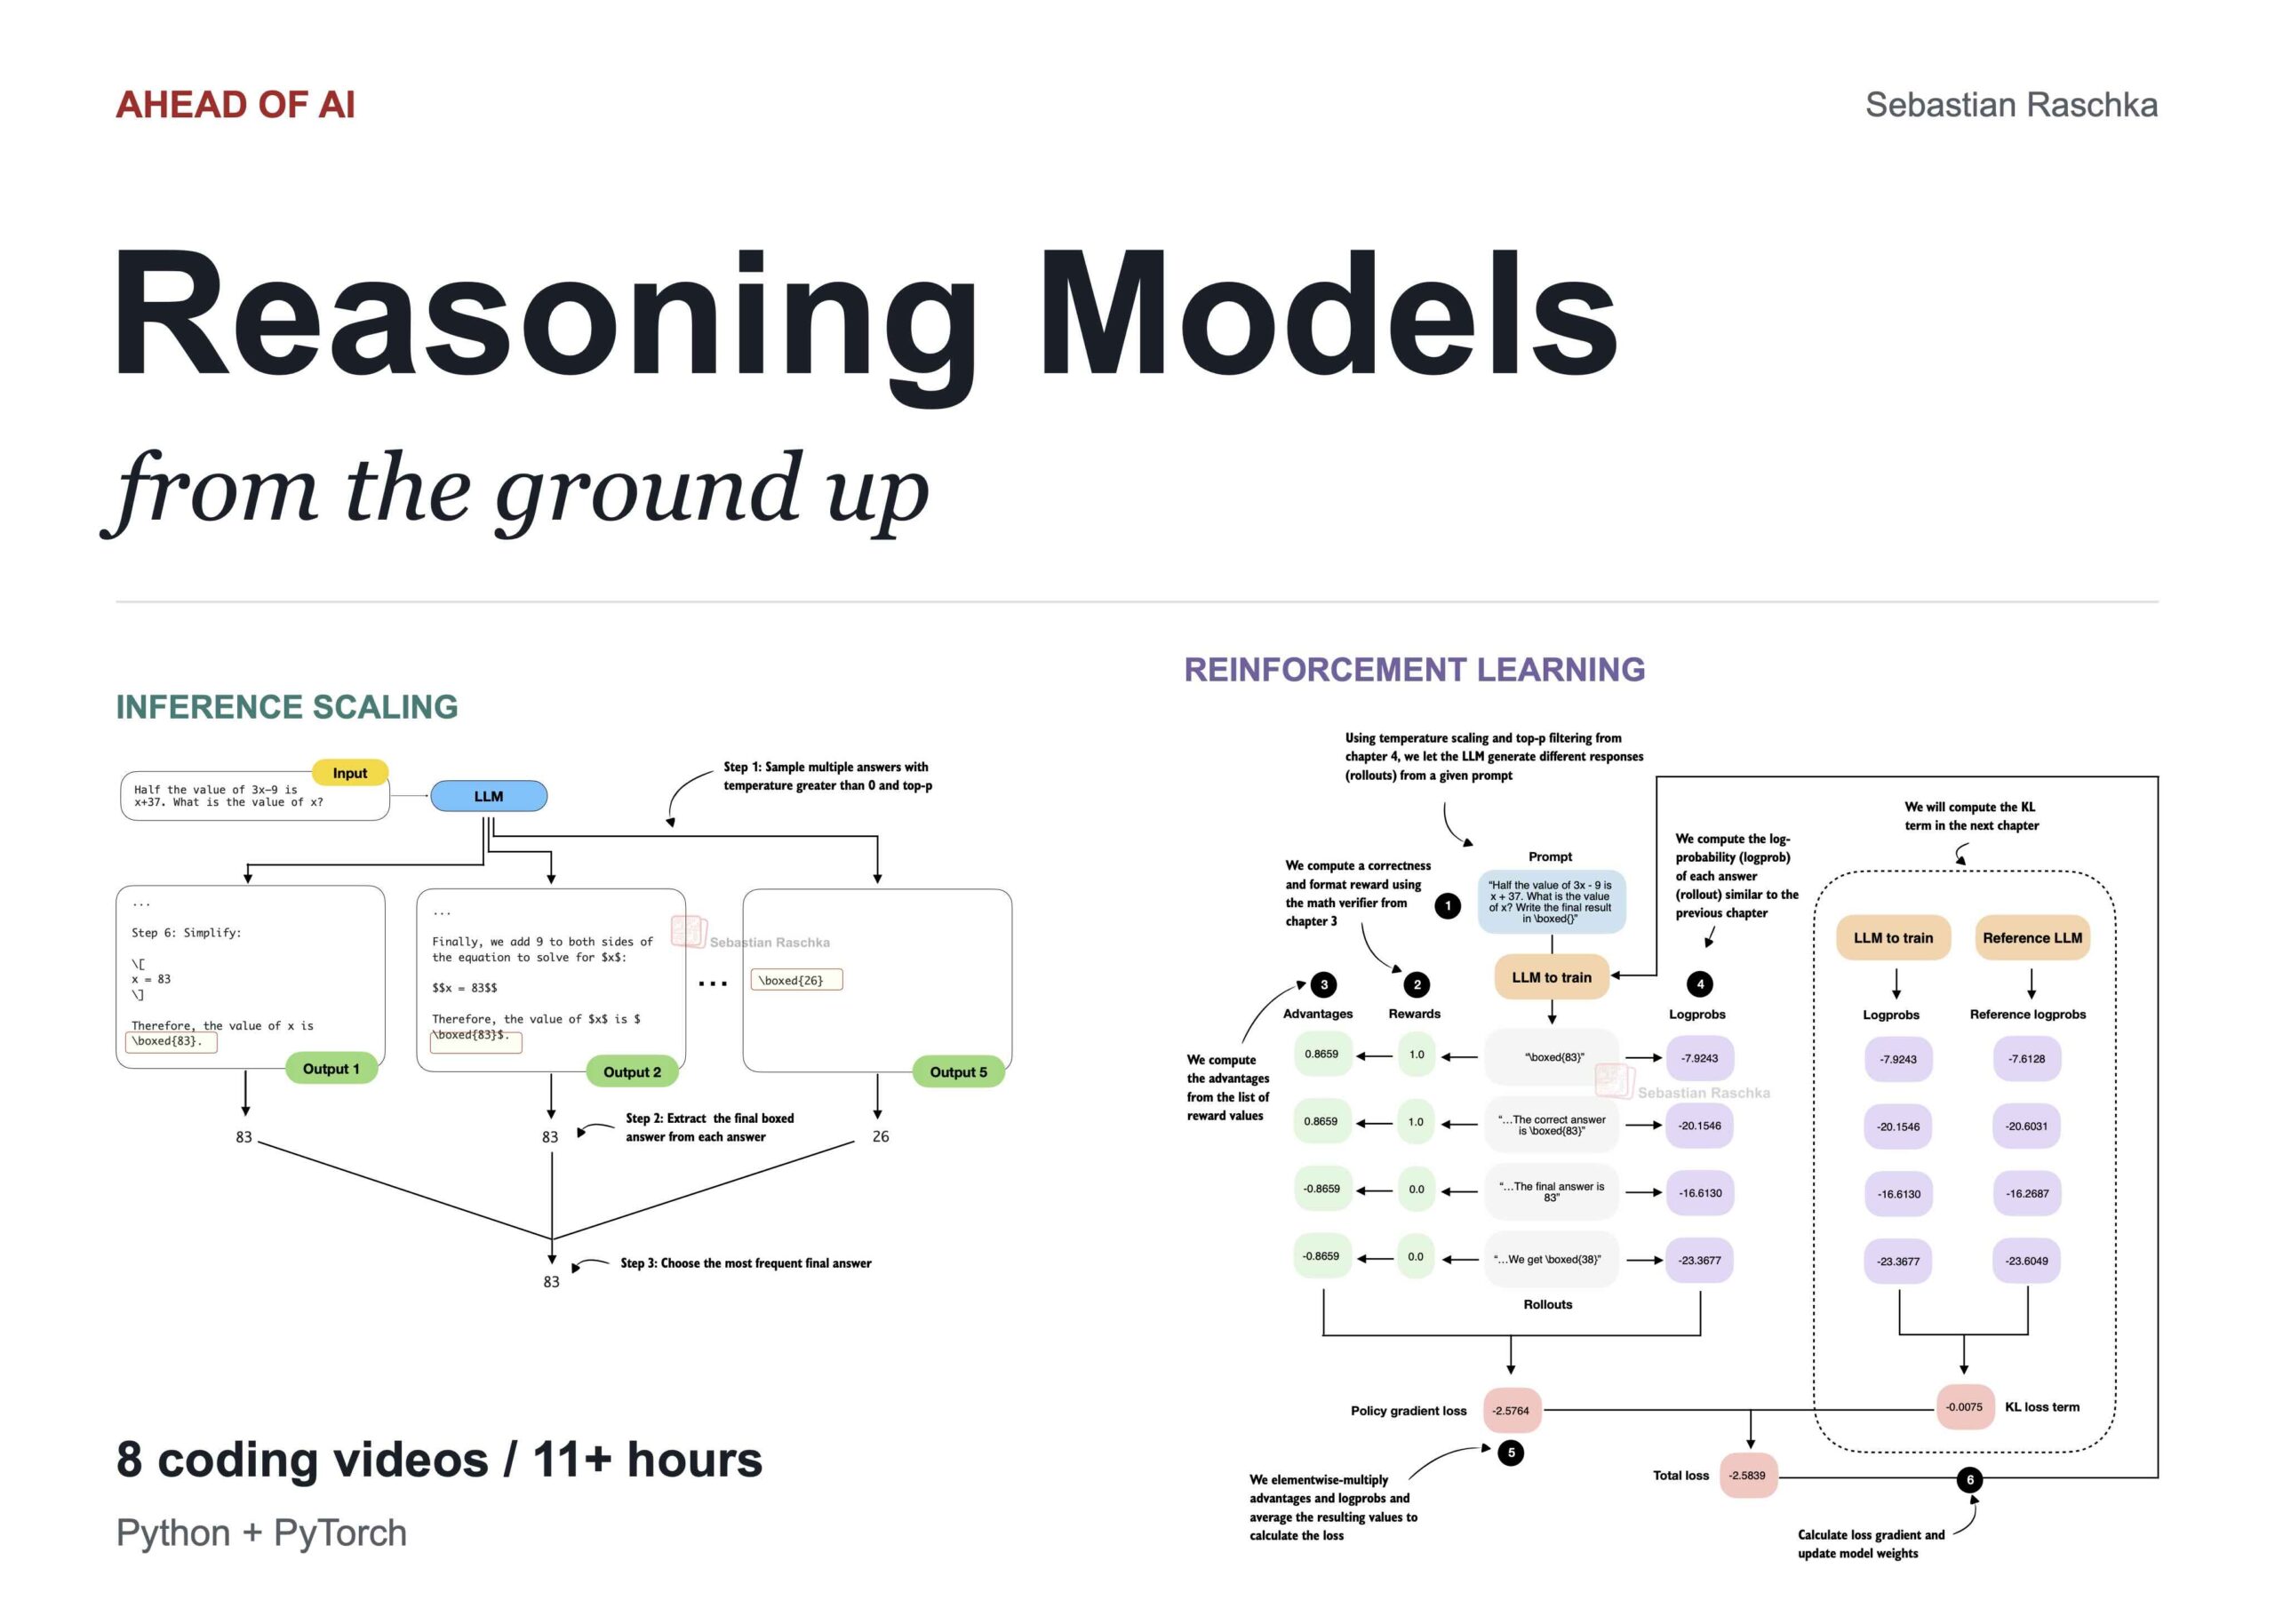
I have written a lot about reasoning models here over the last two years on Ahead of AI, including a…
In this article, you will learn how to turn an open-weight language model into a decision model that classifies user…